A voice agent can speak French, Spanish, or German in a demo and still fail the work it was hired to do. It may choose the wrong language after hearing an accent, cut off a caller who pauses, misread a date or policy, complete a CRM action with the wrong field value, or transfer the caller to a queue that cannot help in that language.
That is why language count is a poor buying criterion. Multilingual readiness is an end-to-end operating capability: the agent must hear, understand, respond, act, document, and escalate reliably in each language and locale you place into service.
The timing matters. Zendesk's September 2026 announcement describes voice as 40% of contact-center volume in its research and introduces real-time two-way translation. Meanwhile, current guidance from AWS, Microsoft, and OpenAI shows that multilingual performance depends on configuration, acoustic conditions, routing, tool behavior, and recordkeeping, not only the underlying model.
For leaders in commercial enterprises and nonprofit foundations, the practical question is not, 'How many languages does the platform list?' It is, 'What evidence proves this service is ready for our callers, policies, systems, and risk profile?' The following ten tests provide that evidence.
First, Define What 'Multilingual' Means
Vendors may use the same word for several different capabilities:
- Recognition: converting the caller's speech into the right words.
- Understanding: mapping those words to the right intent, entities, policy, and next action.
- Response: producing clear speech in the expected language, accent, tone, and locale.
- Translation: converting speech between a caller and a human representative.
- Execution: completing the same business task correctly across languages.
- Operations: routing, monitoring, retaining records, and improving service by language.
A platform may be strong in one layer and weak in another. A high-quality transcript does not prove that an appointment was booked correctly. Natural speech does not prove that a refund policy was applied correctly. A translated conversation does not prove that both the original and translated records follow your retention rules.
Choose the Operating Pattern Before You Test
There are three common patterns. One multilingual agent works well when intents, policies, and integrations are broadly shared and callers may switch languages. Separate agents by locale can be better when regulations, product terms, vocabulary, data residency, or operating ownership differ materially. A real-time translation bridge keeps a human representative in the conversation while extending language coverage.
None is universally best. The architecture determines what can fail, who owns the failure, and which evidence belongs in the release decision. Define the pattern, target languages, supported locales, channels, intents, and escalation model before you set pass thresholds.
The 10 Acceptance Tests
1. Language Entry and Switching
Test: Calls that begin in the default language, begin in a secondary language, switch after several turns, mix languages within a turn, and contain names or borrowed words from another language.
Pass evidence: The agent stays in the intended language, asks a short clarification when confidence is low, preserves context after an intentional switch, and does not change language because of an accent or isolated word. OpenAI's Realtime prompting guidance explicitly separates accent from language and advises against using filler words or isolated foreign words as switch signals.
2. Accent, Dialect, and Real-World Audio
Test: Representative regional accents and dialects, fast and slow speech, hesitant speech, quiet callers, speakerphone audio, background noise, telephone compression, interruptions, and poor network conditions.
Pass evidence: Critical intents and entities remain accurate; the agent confirms uncertain values; and performance is measured by segment rather than averaged into a reassuring global score. Microsoft's September 25 guidance recommends testing accents, speaking rates, quiet speech, noise, telephone audio, and channel-specific failures.
3. Turn-Taking and Interruption
Test: Long pauses, thinking aloud, short answers such as 'yes' or a single digit, interruptions at the start and end of a response, and non-native speakers who need more time to formulate an answer.
Pass evidence: The agent does not repeatedly cut callers off, allows correction, avoids long dead air, and recovers after an interruption without inventing what the caller or agent did not finish saying. Track premature cutoff, barge-in, repeat-prompt, and abandonment by language.
4. Locale-Specific Meaning and Speech
Test: Dates, times, currencies, decimal separators, addresses, phone numbers, personal and place names, product names, acronyms, units, confirmation codes, and formal versus informal forms of address.
Pass evidence: The caller hears the expected local form; ambiguous dates or amounts are confirmed; names and identifiers survive recognition and read-back; and the system stores the canonical value needed by downstream applications.
5. Knowledge and Policy Parity
Test: The same high-volume intents across languages, plus market-specific policy differences. Include refunds, eligibility, opening hours, service boundaries, complaints, safeguarding, and any regulated or mission-critical explanation.
Pass evidence: Answers trace to an approved source, preserve qualifications and exceptions, stay current across translations, and escalate when the knowledge base is missing or contradictory. Native-speaking subject-matter reviewers should judge meaning, not merely grammatical fluency.
6. System-Action Integrity
Test: Bookings, case creation, account lookup, identity verification, status checks, address updates, payment or claim steps, and any write action after a language switch.
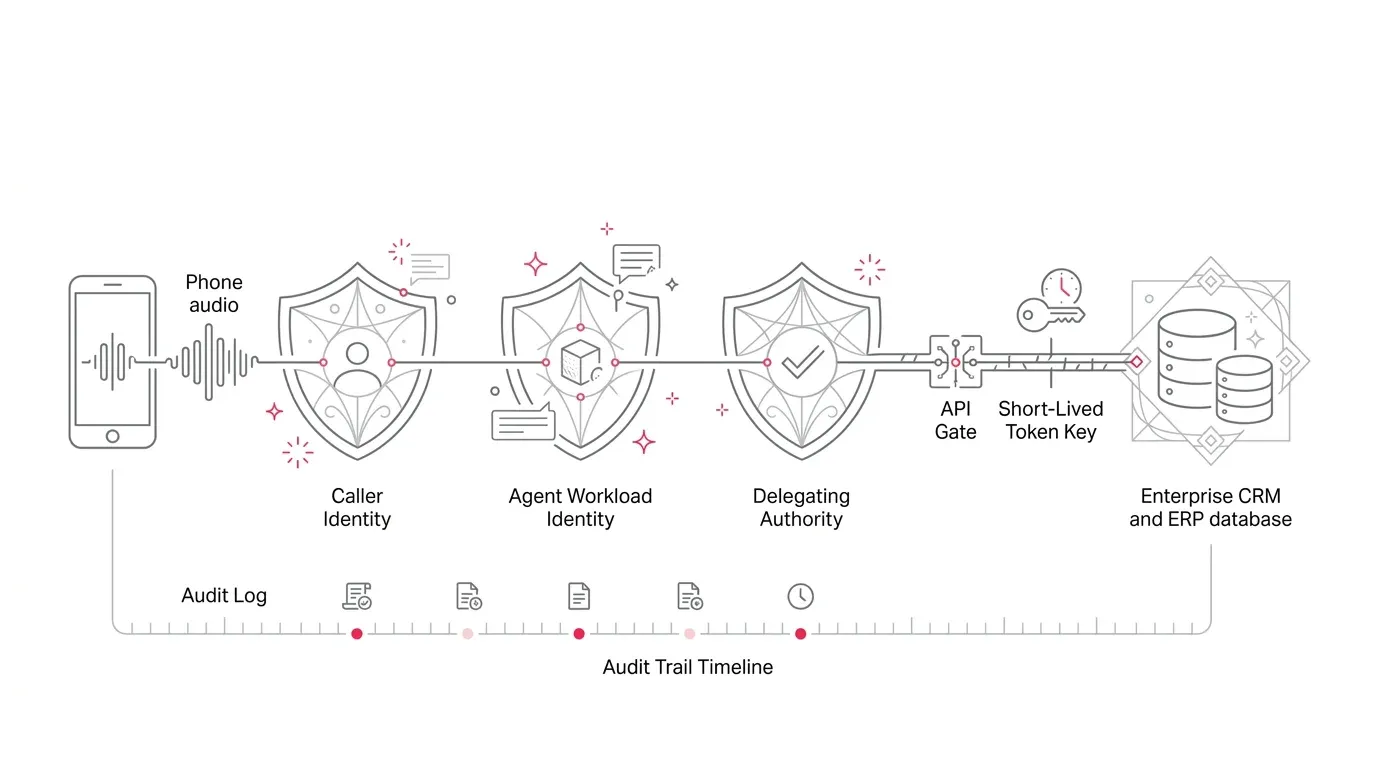
Pass evidence: The agent selects the correct tool, maps entities to the correct fields, seeks confirmation before consequential actions, handles timeouts without claiming success, and produces an auditable result. Measure tool-call accuracy and business-task completion separately from conversation quality.
7. Error Recovery and Safe Boundaries
Test: Unsupported languages, low-confidence recognition, repeated no-match events, unavailable data, tool errors, conflicting records, crisis language, and requests outside the approved scope.
Pass evidence: The agent states the limitation plainly in a language the caller can understand, offers a safe next step, avoids fabricating results, and escalates or stops at a defined boundary. The test plan should include the failure path, not only the happy path.
8. Language-Matched Human Handoff
Test: Caller-requested transfers, policy-driven escalation, low-confidence transfer, after-hours conditions, and unavailable language-qualified representatives.
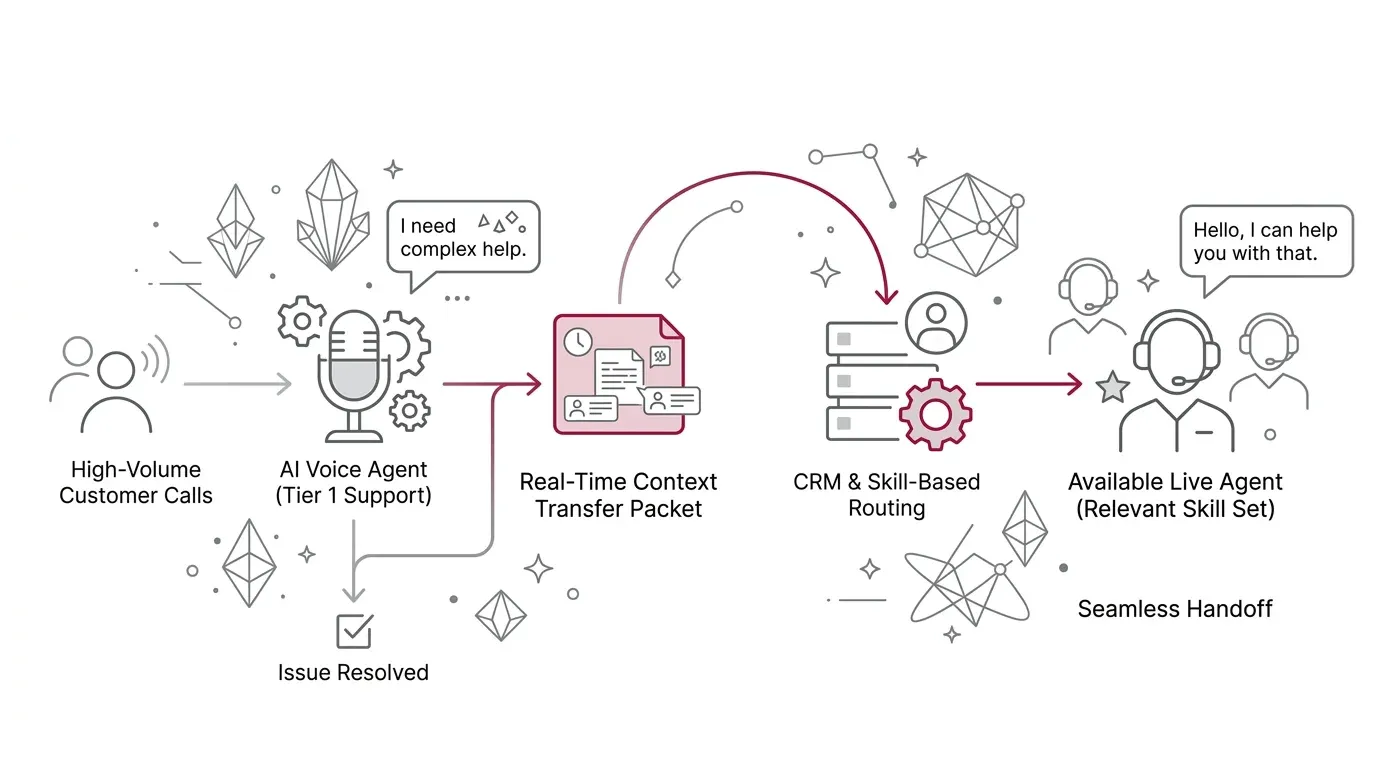
Pass evidence: The correct queue receives the call; the representative can see the caller's language and an accurate summary; the caller does not need to repeat the story; and the fallback is explicit when no qualified person is available. Microsoft's multilingual configuration documentation notes that language-specific routing requires corresponding queues and qualified representatives.
9. Transcript, Translation, Privacy, and Retention
Test: Language switches in the transcript, original versus translated audio, redaction, retention periods, deletion, access controls, investigation logs, and regional storage requirements.
Pass evidence: The organization can explain which artifacts exist, which version is authoritative, who can access them, where they are stored, and when they are deleted. A transcript should not silently fall back to the wrong language or lose the switch point. Zendesk's translation announcement, for example, makes retention of original and translated audio an explicit administrative choice.
10. Per-Language Metrics and Release Control
Test: Dashboards and release reports segmented by language, locale, intent, channel, and risk tier. Re-run the suite after model, prompt, voice, knowledge, telephony, or integration changes.
Pass evidence: Leaders can see task completion, critical-entity accuracy, wrong-language rate, time to first audio, cutoff and barge-in rates, tool success, transfer success, repeat calls, and customer outcomes for each production language. Every release has an owner, version, monitoring plan, and tested rollback path.
Use a Release Matrix, Not a Single Average
Set thresholds before the pilot begins. A useful scorecard gives every language and high-value intent its own release status:
| Gate | Evidence to retain | Release question |
|---|---|---|
| Conversation | Audio, transcript, language events, interruption traces | Can callers complete the flow under representative speech and channel conditions? |
| Meaning | Approved answer, source, reviewer result, exception handling | Is the policy meaning correct and complete in this locale? |
| Action | Tool input/output, confirmation, final system state | Did the system perform the intended task without an unsafe side effect? |
| Handoff | Queue, summary, language tag, representative outcome | Can the caller reach competent human support with context intact? |
| Governance | Version, approver, retention setting, monitoring owner | Can the organization explain and control what was released? |
Avoid hiding a weak language inside a portfolio average. A language with lower volume can still carry high reputational, accessibility, or service risk. Release it only when the relevant workflow passes, or narrow the scope and provide a clear human alternative.
How to Run a Multilingual Voice AI Pilot
- Prioritize languages with call-volume, wait-time, after-hours, mission-access, or expansion value. Define locale variants explicitly.
- Choose three to five representative intents, including at least one read-only task, one write action, and one human handoff.
- Build a test set from consented, appropriately handled real-world patterns. Include edge cases and native-speaking reviewers.
- Agree thresholds and stop conditions before listening to the best demo calls.
- Run on the real telephony path and connected systems in a controlled environment.
- Review failures by layer: recognition, language control, knowledge, tool use, routing, or records. Fix the layer that failed.
- Release language by language and intent by intent, with monitoring and rollback in place.
Applying the Framework to YuniQ
YuniQ's customer care automation page says its voice agent is trained on an organization's telephony data, call scripts, CRM data, FAQs, and knowledge base; can connect to live business systems; and can transfer a caller with a conversation summary. It also offers a working proof of concept in 48–72 hours and local or private-cloud deployment options.
Those published capabilities make a POC the right place to run this acceptance matrix. Language coverage is not specified on the canonical page, so confirm the current supported languages, locales, voices, telephony paths, deployment regions, and retention options during scoping. Then test the selected combination with your own intents, policies, vocabulary, and systems.
Recommended CTA: Request a working YuniQ voice-agent POC and use these ten tests as the release gate for each target language.
FAQ
What is multilingual voice AI?
Multilingual voice AI is a voice-agent capability that recognizes and understands speech, responds in one or more languages, and completes or routes a task. Some systems use a native multilingual model; others use separate locale-specific agents or a translation layer.
Is automatic language detection enough?
No. Detection must be tested with accents, short utterances, names, background noise, and code-switching. The agent also needs a clarification path when confidence is low and a stable policy for when it should change languages.
Should we measure word error rate?
Word error rate can help diagnose recognition, but it is not a complete business metric. Pair it with intent accuracy, critical-entity accuracy, task completion, tool-call success, handoff success, latency, repeat calls, and customer outcomes by language.
Do we need a separate agent for every language?
Not necessarily. One multilingual agent can reduce maintenance when workflows and policies are shared. Separate locale-specific agents may be easier to govern when policies, vocabularies, teams, or data requirements differ. The acceptance tests should determine which pattern is operationally sound.
How many languages should a pilot include?
Start with the languages tied to the clearest service problem or business value, and keep the workflow narrow enough to test deeply. It is better to prove a few high-value language and intent combinations than to demonstrate shallow coverage across a long list.